Fetch Zookeeper information from Python with Kazoo to connect Hive
Table of contents
Preamble
Straight from the beginning when I have landed to our Hadoop project (HortonWorks) I have seen all our Python scripts directly connecting to our Hive server, with PyHive, bypassing Zookeeper coordination. I also noticed that every Beeline client connection where well using (obviously) the HiveServer2 JDBC URL. I have left this point open for later until we decided to improve our High Availability (HA) by making few components running on multiple servers. And when it came to our HiveServer2 that is now running on two edge nodes of our Hadoop cluster I have decided to dig out this thread…
The good way of connecting to HiveServer2 is to first get current status and configuration from Zookeeper and then use this information in PyHive (for example) to make a Hive connection. Zookeeper is acting here as a configuration keeper as well as an availability watcher, means Zookeeper will not return a dead HiveServer2 information.
Digging a bit on Internet I came quickly to the obvious conclusion that Kazoo Python package was a must try !
This blog post has been written using kazoo 2.5.0, Python 3.7.3. My Hadoop cluster is HortonWorks Data Platform (HDP) 2.6.4. All developed scripts are running on a Fedora 30 virtual machine.
Kazoo development environment installation
Anaconda is the preferred Python 3.7 environment management so started by downloading and installing it for Python 3.7 on my Fedora virtual machine. The release I have installed is:
[root@fedora1 ~]# anaconda --version anaconda 30.25.6
It also gives you access to conda that is command line environment management:
(base) [root@fedora1 ~]# conda --version
conda 4.6.14
(base) [root@fedora1 ~]# conda info
active environment : base
active env location : /opt/anaconda3
shell level : 1
user config file : /root/.condarc
populated config files : /root/.condarc
conda version : 4.6.14
conda-build version : 3.17.8
python version : 3.7.3.final.0
base environment : /opt/anaconda3 (writable)
channel URLs : https://repo.anaconda.com/pkgs/main/linux-64
https://repo.anaconda.com/pkgs/main/noarch
https://repo.anaconda.com/pkgs/free/linux-64
https://repo.anaconda.com/pkgs/free/noarch
https://repo.anaconda.com/pkgs/r/linux-64
https://repo.anaconda.com/pkgs/r/noarch
package cache : /opt/anaconda3/pkgs
/root/.conda/pkgs
envs directories : /opt/anaconda3/envs
/root/.conda/envs
platform : linux-64
user-agent : conda/4.6.14 requests/2.21.0 CPython/3.7.3 Linux/5.0.11-300.fc30.x86_64 fedora/30 glibc/2.29
UID:GID : 0:0
netrc file : None
offline mode : False
As I am behind a corporate proxy I had to customize a little bit my .condarc profile:
(base) [root@fedora1 ~]# cat .condarc
ssl_verify: False
proxy_servers:
http: http://proxy_user:proxy_password@proxy_server:proxy_port
https: https://proxy_user:proxy_password@proxy_server:proxy_port
Remark
I have also been obliged to set ssl_verify to false to avoid any certificate issues that are not in my proxy server…
I create a kazoo conda environment with:
(base) [root@fedora1 ~]# conda create -n kazoo Collecting package metadata: done Solving environment: done ## Package Plan ## environment location: /opt/anaconda3/envs/kazoo Proceed ([y]/n)? y Preparing transaction: done Verifying transaction: done Executing transaction: done # # To activate this environment, use # # $ conda activate kazoo # # To deactivate an active environment, use # # $ conda deactivate
Activate it with:
[root@fedora1 ~]# conda activate kazoo (kazoo) [root@fedora1 ~]#
As you have seen I am working with root which is a very bad idea so better to use a normal account (and keep root for more important tasks see below), to do so initialize Conda with (my shell is obviously bash):
[yjaquier@fedora1 ~]$ /opt/anaconda3/bin/conda init bash no change /opt/anaconda3/condabin/conda no change /opt/anaconda3/bin/conda no change /opt/anaconda3/bin/conda-env no change /opt/anaconda3/bin/activate no change /opt/anaconda3/bin/deactivate no change /opt/anaconda3/etc/profile.d/conda.sh no change /opt/anaconda3/etc/fish/conf.d/conda.fish no change /opt/anaconda3/shell/condabin/Conda.psm1 no change /opt/anaconda3/shell/condabin/conda-hook.ps1 no change /opt/anaconda3/lib/python3.7/site-packages/xonsh/conda.xsh no change /opt/anaconda3/etc/profile.d/conda.csh modified /home/yjaquier/.bashrc ==> For changes to take effect, close and re-open your current shell. <==
Logoff and logon again and use the newly created environment with:
(base) [yjaquier@fedora1 ~]$ conda activate kazoo (kazoo) [yjaquier@fedora1 ~]$
You also need to configure your conda environment (.condarc) same as above...
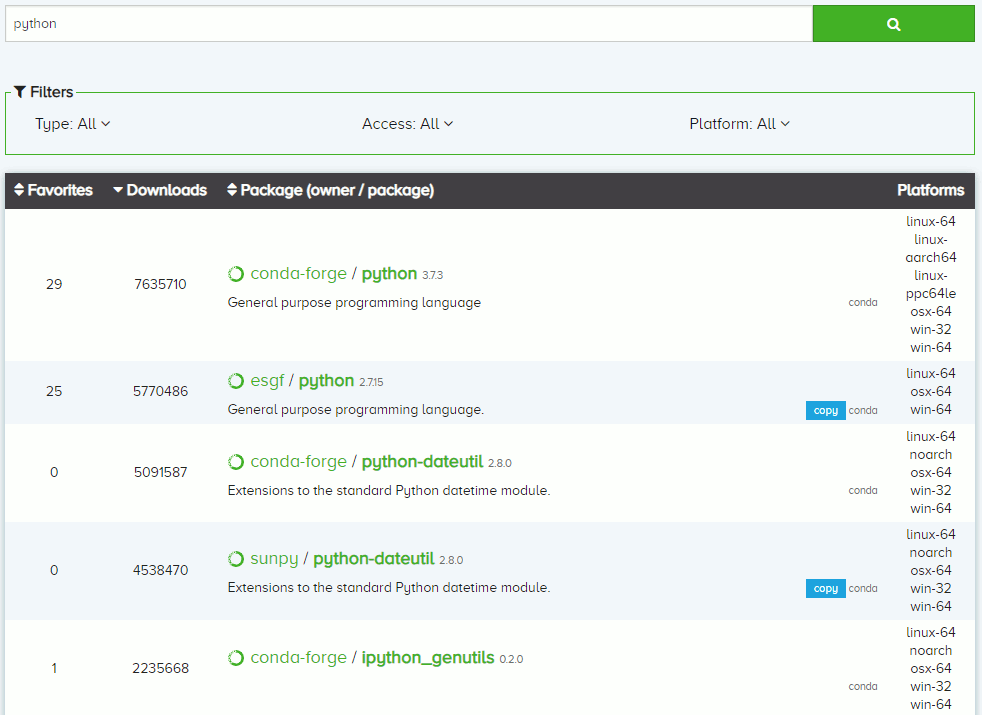
For package management and search your reference will be https://anaconda.org. Here is an example of a search for Python (direct link is https://anaconda.org/search?q=python):

If you enter in the Python package most downloaded (good practice in my opinion) you will find the command to install it:
conda install -c conda-forge python
But then you cannot modify the environment with your own account and packages add must be done by root, which is, in my opinion, a very good practice:
EnvironmentNotWritableError: The current user does not have write permissions to the target environment. environment location: /opt/anaconda3/envs/kazoo uid: 1000 gid: 100
So executing with root account (in kazoo conda environment):
(kazoo) [root@fedora1 ~]# conda install -c conda-forge python
Collecting package metadata: done
Solving environment: done
## Package Plan ##
environment location: /opt/anaconda3/envs/kazoo
added / updated specs:
- python
The following packages will be downloaded:
package | build
---------------------------|-----------------
bzip2-1.0.6 | h14c3975_1002 415 KB conda-forge
certifi-2019.3.9 | py37_0 149 KB conda-forge
pip-19.1 | py37_0 1.8 MB conda-forge
python-3.7.3 | h5b0a415_0 35.7 MB conda-forge
setuptools-41.0.1 | py37_0 616 KB conda-forge
wheel-0.33.1 | py37_0 34 KB conda-forge
------------------------------------------------------------
Total: 38.7 MB
The following NEW packages will be INSTALLED:
bzip2 conda-forge/linux-64::bzip2-1.0.6-h14c3975_1002
ca-certificates conda-forge/linux-64::ca-certificates-2019.3.9-hecc5488_0
certifi conda-forge/linux-64::certifi-2019.3.9-py37_0
libffi conda-forge/linux-64::libffi-3.2.1-he1b5a44_1006
libgcc-ng pkgs/main/linux-64::libgcc-ng-8.2.0-hdf63c60_1
libstdcxx-ng pkgs/main/linux-64::libstdcxx-ng-8.2.0-hdf63c60_1
ncurses conda-forge/linux-64::ncurses-6.1-hf484d3e_1002
openssl conda-forge/linux-64::openssl-1.1.1b-h14c3975_1
pip conda-forge/linux-64::pip-19.1-py37_0
python conda-forge/linux-64::python-3.7.3-h5b0a415_0
readline conda-forge/linux-64::readline-7.0-hf8c457e_1001
setuptools conda-forge/linux-64::setuptools-41.0.1-py37_0
sqlite conda-forge/linux-64::sqlite-3.26.0-h67949de_1001
tk conda-forge/linux-64::tk-8.6.9-h84994c4_1001
wheel conda-forge/linux-64::wheel-0.33.1-py37_0
xz conda-forge/linux-64::xz-5.2.4-h14c3975_1001
zlib conda-forge/linux-64::zlib-1.2.11-h14c3975_1004
Proceed ([y]/n)? y
Downloading and Extracting Packages
python-3.7.3 | 35.7 MB | #################################################################################################################################################################### | 100%
certifi-2019.3.9 | 149 KB | #################################################################################################################################################################### | 100%
wheel-0.33.1 | 34 KB | #################################################################################################################################################################### | 100%
setuptools-41.0.1 | 616 KB | #################################################################################################################################################################### | 100%
pip-19.1 | 1.8 MB | #################################################################################################################################################################### | 100%
bzip2-1.0.6 | 415 KB | #################################################################################################################################################################### | 100%
Preparing transaction: done
Verifying transaction: done
Executing transaction: done
I have also installed Kazoo using:
(kazoo) [root@fedora1 ~]# conda install -c conda-forge kazoo
And I have also installed PyHive to connect to Hive, Pandas to manipulate data structures (finally I have not used it at the end):
conda install -c anaconda pyhive conda install -c conda-forge pandas
Python source code
The small source code (kazoo_testing.py file name in below) I have written is mainly coming (for the Kazoo part) from the official documentation so no restriction to visit it:
from kazoo.client import KazooClient,KazooState
def my_listener(state):
if state == KazooState.LOST:
# Register somewhere that the session was lost
print('Connection lost !!')
elif state == KazooState.SUSPENDED:
# Handle being disconnected from Zookeeper
print('Connection suspended !!')
else:
# Handle being connected/reconnected to Zookeeper
print('Connected !!')
zk = KazooClient(hosts='zookeeper_server01.domain.com:2181,zookeeper_server02.domain.com:2181,zookeeper_server03.domain.com:2181')
zk.add_listener(my_listener)
#zk.start()
zk.start(timeout=5)
# Display Zookeeper information
print(zk.get_children('/'))
#print(zk.get_children('hiveserver2')[0])
print(zk.get_children(path='hiveserver2'))
for hiveserver2 in zk.get_children(path='hiveserver2'):
array01=hiveserver2.split(';')[0].split('=')[1].split(':')
hive_hostname=array01[0]
hive_port=array01[1]
print('Hive hostname: ' + hive_hostname)
print('Hive port: ' + hive_port)
The list of Zookeeper server can be taken from the Hive Ambari page where you can copy/paste the so called HIVESERVER2 JDBC URL.
The above source code does not include the PyHive connection but once you get the Hive host name and port you can easily connect with something like (configuration parameter is optional):
from pyhive import hive
# Hive connection
connection=hive.connect(
host = hive_hostname,
port = hive_port,
configuration={'tez.queue.name': 'your_yarn_queue_name'},
username = "your_account"
)
pandas01=pd.read_sql("select * from ...", connection)
print(pandas01.sample(10))
Kazoo testing
I have the chance to have configured two HiveServer2 in my Hortonworks Hadoop cluster. Which is, by the way, strongly suggested if you aim to be Highly Available (HA). When the two HiveServer2 processes are up and running I get below result:
(kazoo) [yjaquier@fedora1 ~]$ python kazoo_testing.py Connected !! ['registry', 'cluster', 'brokers', 'storm', 'zookeeper', 'infra-solr', 'hbase-unsecure', 'tracers', 'hadoop-ha', 'admin', 'isr_change_notification', 'accumulo', 'logsearch', 'controller_epoch', 'hiveserver2', 'druid', 'rmstore', 'ambari-metrics-cluster', 'consumers', 'config'] ['serverUri=hiveserver201.domain.com:10000;version=1.2.1000.2.6.4.0-91;sequence=0000000042', 'serverUri=hiveserver202.domain.com:10000;version=1.2.1000.2.6.4.0-91;sequence=0000000043'] Hive hostname: hiveserver201.domain.com Hive port: 10000 Hive hostname: hiveserver202.domain.com Hive port: 10000
If I stop the first HiverServer2, after a while, I suppose the time for Zookeeper to get and propagate the information I finally get:
(kazoo) [yjaquier@fedora1 ~]$ python kazoo_testing.py Connected !! ['registry', 'cluster', 'brokers', 'storm', 'zookeeper', 'infra-solr', 'hbase-unsecure', 'tracers', 'hadoop-ha', 'admin', 'isr_change_notification', 'accumulo', 'logsearch', 'controller_epoch', 'hiveserver2', 'druid', 'rmstore', 'ambari-metrics-cluster', 'consumers', 'config'] ['serverUri=hiveserver202.domain.com:10000;version=1.2.1000.2.6.4.0-91;sequence=0000000042'] Hive hostname: hiveserver202.domain.com Hive port: 10000


